WordPress Robots.txt Guide – What It Is and How to Use It
- Category : SEO
- Posted on : Apr 18, 2018
- Views : 3,410
- By : Zane P.

Ever heard the term robots.txt and wondered how it applies to your website? Most websites have a robots.txt file, but that doesn’t mean most webmasters understand it. In this post, we hope to change that by offering a deep dive into the WordPress robots.txt file, as well as how it can control and limit access to your site. By the end, you’ll be able to answer questions like:
- What is a WordPress Robots.txt?
- How Does Robots.txt Help My Website?
- How Can I Add Robots.txt To WordPress?
- What Sorts Of Rules Can I Put In Robots.txt?
- How Do I Test My Robots.txt File?
- How Do Big WordPress Websites Implement Robots.txt?
There’s a lot to cover so let’s get started!
What Is a WordPress Robots.txt?
Before we can talk about the WordPress robots.txt, it’s important to define what a “robot” is in this case. Robots are any type of “bot” that visits websites on the Internet. The most common example is search engine crawlers. These bots “crawl” around the web to help search engines like Google index and rank the billions of pages on the Internet.
So, bots are, in general, a good thing for the Internet…or at least a necessary thing. But that doesn’t necessarily mean that you, or other webmasters, want bots running around unfettered. The desire to control how web robots interact with websites led to the creation of the robots exclusion standard in the mid-1990s. Robots.txt is the practical implementation of that standard – it allows you to control how participating bots interact with your site. You can block bots entirely, restrict their access to certain areas of your site, and more.
That “participating” part is important, though. Robots.txt cannot force a bot to follow its directives. And malicious bots can and will ignore the robots.txt file. Additionally, even reputable organizations ignore some commands that you can put in Robots.txt. For example, Google will ignore any rules that you add to your robots.txt about how frequently its crawlers visit. If you are having a lot of issues with bots, a security solution such as Cloudflare or Sucuri can come in handy.
Why Should You Care About Your Robots.txt File?
For most webmasters, the benefits of a well-structured robots.txt file boil down to two categories:
- Optimizing search engines’ crawl resources by telling them not to waste time on pages you don’t want to be indexed. This helps ensure that search engines focus on crawling the pages that you care about the most.
- Optimizing your research usage by blocking bots that are wasting your server resources.
Robots.txt Isn’t Specifically About Controlling Which Pages Get Indexed In Search Engines
Robots.txt is not a foolproof way to control what pages search engines index. If your primary goal is to stop certain pages from being included in search engine results, the proper approach is to use a meta noindex tag or another similarly direct method.
This is because your Robots.txt is not directly telling search engines not to index content – it’s just telling them not to crawl it. While Google won’t crawl the marked areas from inside your site, Google itself states that if an external site links to a page that you exclude with your Robots.txt file, Google still might index that page.
John Mueller, a Google Webmaster Analyst, has also confirmed that if a page has links pointed to it, even if it’s blocked by robots.txt, might still get indexed. Below is what he had to say in a Webmaster Central hangout:
One thing maybe to keep in mind here is that if these pages are blocked by robots.txt, then it could theoretically happen that someone randomly links to one of these pages. And if they do that then it could happen that we index this URL without any content because its blocked by robots.txt. So we wouldn’t know that you don’t want to have these pages actually indexed.
Whereas if they’re not blocked by robots.txt you can put a noindex meta tag on those pages. And if anyone happens to link to them, and we happen to crawl that link and think maybe there’s something useful here then we would know that these pages don’t need to be indexed and we can just skip them from indexing completely.
So, in that regard, if you have anything on these pages that you don’t want to have indexed then don’t disallow them, use noindex instead.
How To Create And Edit Your WordPress Robots.txt File
By default, WordPress automatically creates a virtual robots.txt file for your site. So even if you don’t lift a finger, your site should already have the default robots.txt file. You can test if this is the case by appending “/robots.txt” to the end of your domain name.
Because this file is virtual, though, you can’t edit it. If you want to edit your robots.txt file, you’ll need to actually create a physical file on your server that you can manipulate as needed. Here are three simple ways to do that…
How to Create And Edit A Robots.txt File With Yoast SEO
If you’re using the popular Yoast SEO plugin, you can create (and later edit) your robots.txt file right from Yoast’s interface. Before you can access it, though, you need to enable Yoast SEO’s advanced features by going to SEO → Dashboard → Features and toggling on Advanced settings pages:

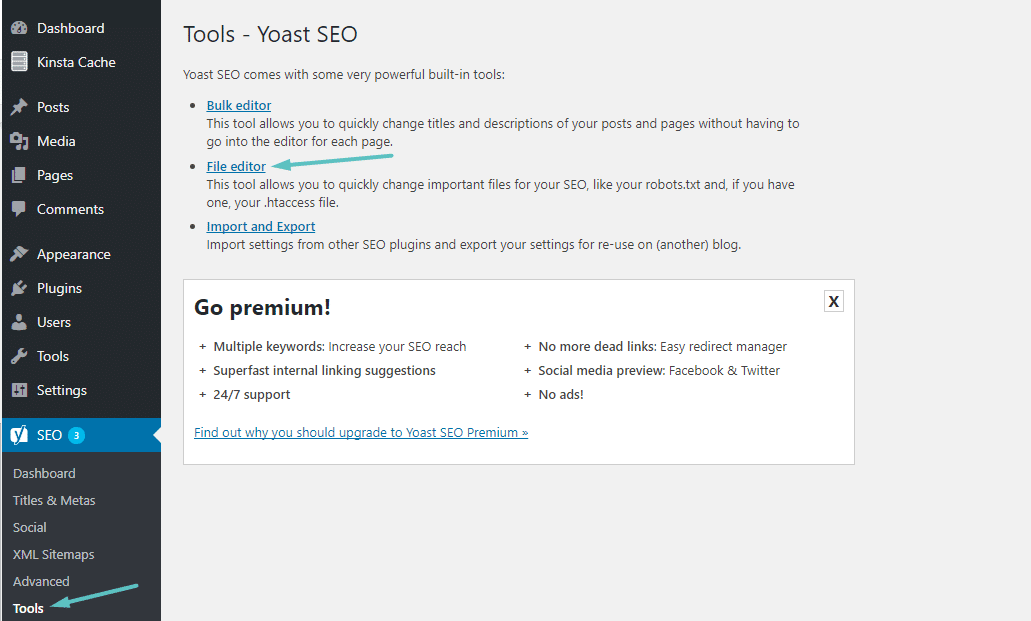
Once that’s activated, you can go to SEO → Tools and click on File editor:
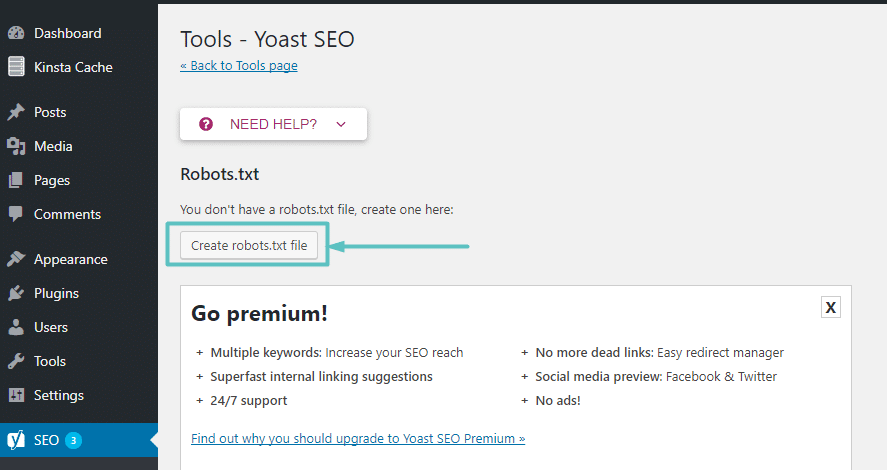
Assuming you don’t already have a physical Robots.txt file, Yoast will give you an option to Create robots.txt file:
And once you click that button, you’ll be able to edit the contents of your Robots.txt file directly from the same interface:
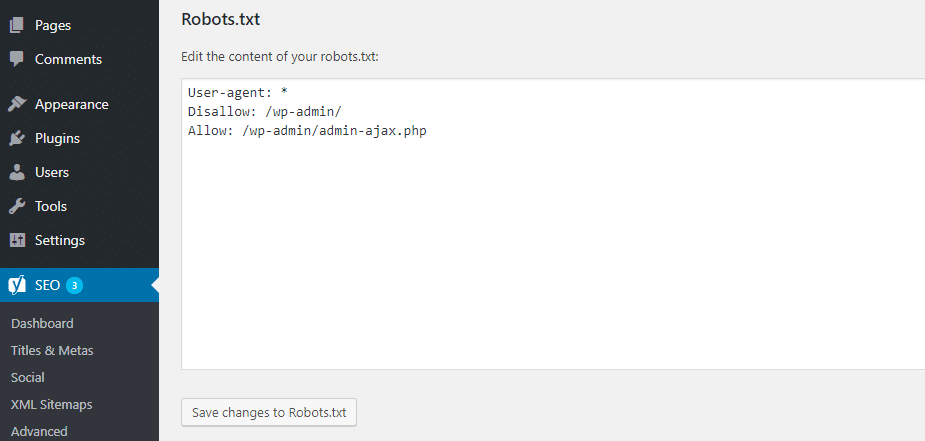
As you read on, we’ll dig more into what types of directives to put in your WordPress robots.txt file.
How to Create And Edit A Robots.txt File With All In One SEO
If you’re using the almost-as-popular-as-Yoast All in One SEO Pack plugin, you can also create and edit your WordPress robots.txt file right from the plugin’s interface. All you need to do is go to All in One SEO → Feature Manager and Activate the Robots.txt feature: