What Is HTTP/3 – Lowdown on the Fast New UDP-Based Protocol
- Category : General
- Posted on : Apr 24, 2019
- Views : 3,571
- By : Zane P.
TL;DR
In November 2018, the Internet Engineering Task Force (IETF) met in Bangkok, and a new Internet Draft was adopted. The QUIC transport protocol, an HTTP/2successor, was renamed to HTTP/3. HTTP/3 builds on UDP, and is already being used by prominent internet companies such as Google and Facebook. If you’re using Chrome and connecting to a Google service, you’re probably already using QUIC.
The new version of the HTTP protocol benefits from the bare-metal, low-level UDP protocol, and defines many of the new features which were in previous versions of HTTP at the TCP layer. This provides a way of solving constraints within the existing internet infrastructure.
The first results are promising, and when the Internet Draft by IETF expires, in June 2019, we can expect HTTP/3 to be promoted as a new, third generation HTTP standard.
- HTTP/3 Is Coming
- What is HTTP/3 – In Layman’s Terms
- A Bit of Background – It Started with HTTP/2
- Internet Protocol (IP)
- Understanding the Role of TCP and UDP
- QUIC and HTTP/3
HTTP/3 Is Coming
Some say that the web industry’s hunger for more speed and lower latency is only matched by Google Chrome’s hunger for more RAM.
In 2016, we published an article about HTTP/2, a standard that, according to W3Techs, currently has around a 34% world adoption rate. And according to Can I use, it’s also supported by all modern web browsers. Yet here we are, writing an article about the next version of the protocol, HTTP/3.
HTTP/3 is, at the time of this writing, an IETF Internet-Draft or ID, which means that it is currently under consideration for an upcoming internet standard by the Internet Engineering Task Force – an international internet standards body, in charge of defining and promoting agreed upon internet protocol standards, such as TCP, IPv6, VoIP, Internet of Things, etc.
It is an open body which unites the web industry and facilitates discussion about the direction of the internet.
Currently, the ID phase of HTTP/3 is the last phase before proposals are promoted to the level of RFC-s, or Request-for-Comments, which we can consider, for all intents and purposes, official internet protocol definitions. Then are then implemented by all major internet players.
This means that HTTP/3 is to become an official standard once the draft expires later this year (June 2019).
What is HTTP/3 - In Layman's Terms
HTTP/3 is the third version of the Hypertext Transfer Protocol (HTTP), previously known as HTTP-over-QUIC. QUIC (Quick UDP Internet Connections) was initially developed by Google and is the successor of HTTP/2. Companies such as Google and Facebook have already been using QUIC to speed up the web.
A Bit of Background – It Started with HTTP/2
At Host SEO we are obsessed with squeezing every last millisecond from our stack, whether it’s taking advantage of the newest version of PHP, delivering data over Google Cloud Platform’s premium tier network, or caching assets on our HTTP/2 CDN.
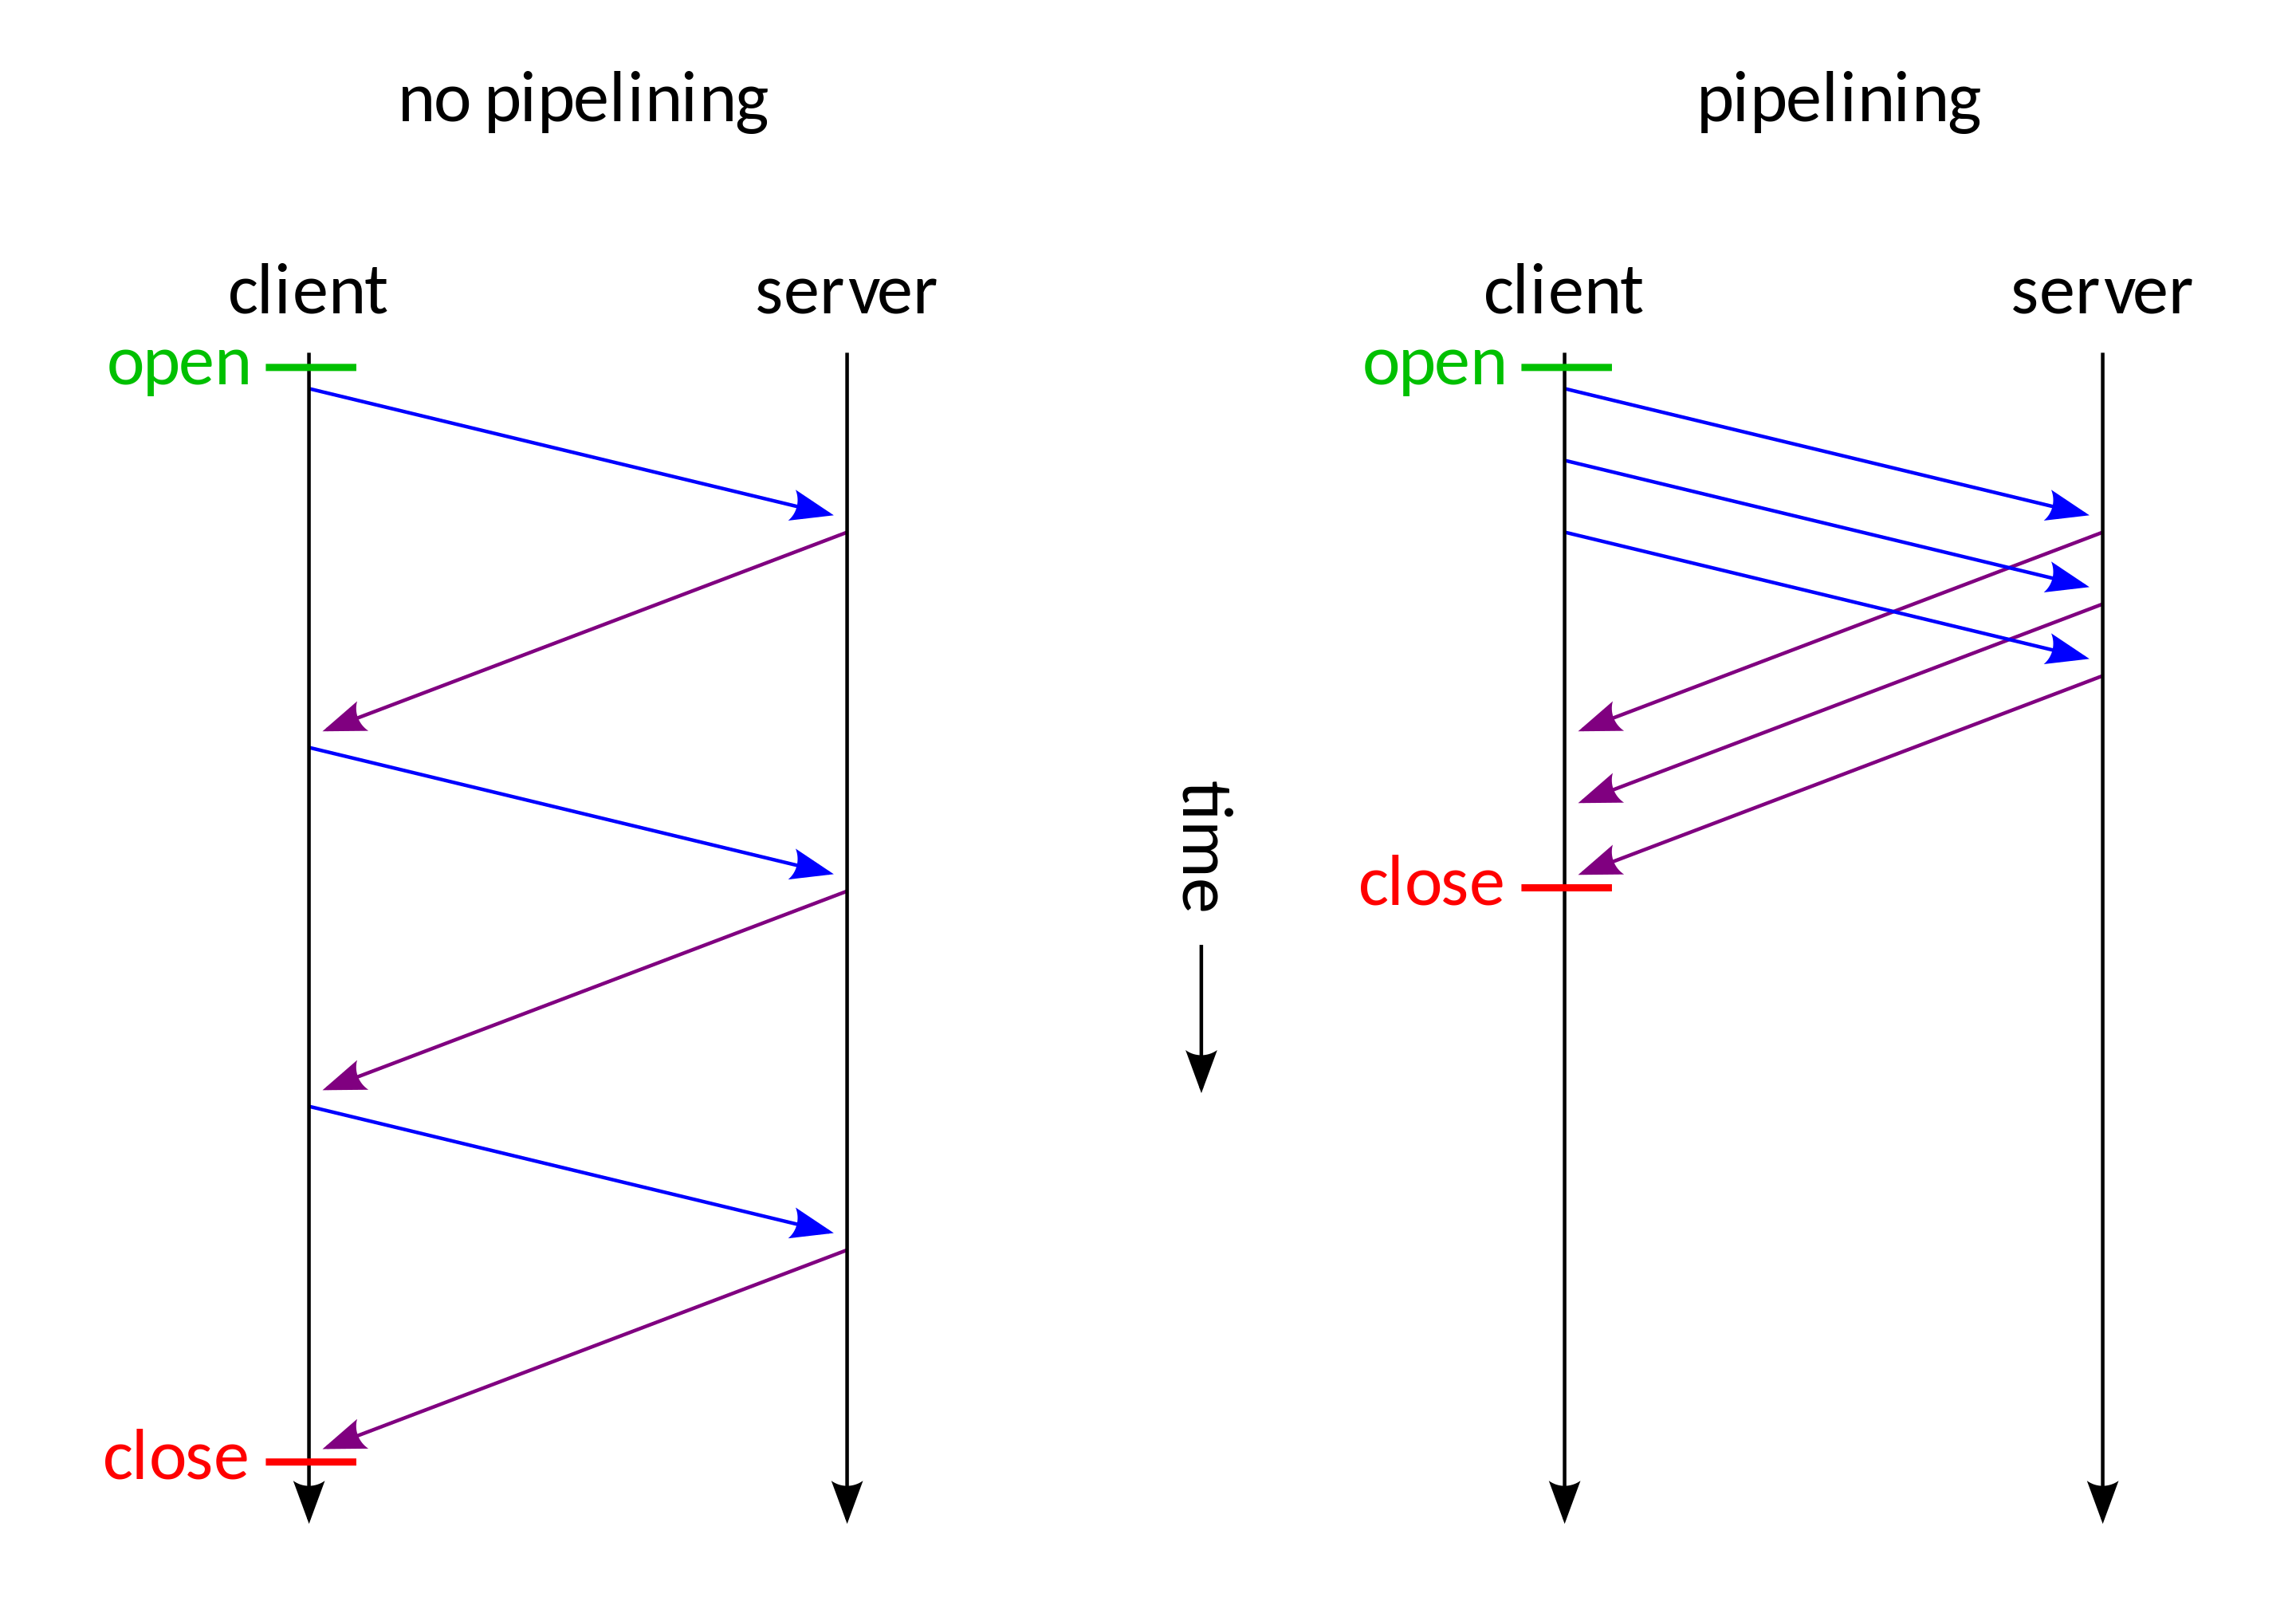
HTTP/2 brought some serious improvements with non-blocking downloads, pipelining, and server push which has helped us overcome some limitations of the underlying TCP protocol. It allowed us to minimize the number of request-response cycles and handshakes.
HTTP/2 made it possible to push more than one resource in a single TCP connection – multiplexing. We also got more flexibility in the ordering of static downloads, and our pages are now no longer constrained by a linear progression of the downloads.
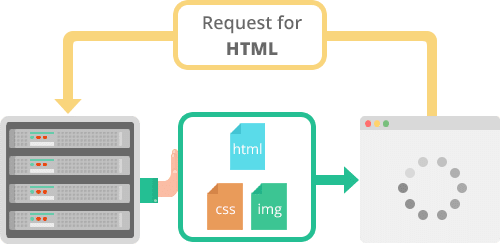
In practice, this means that now one large javascript resource does not necessarily equal a choke point for all the other static resources waiting their turn.
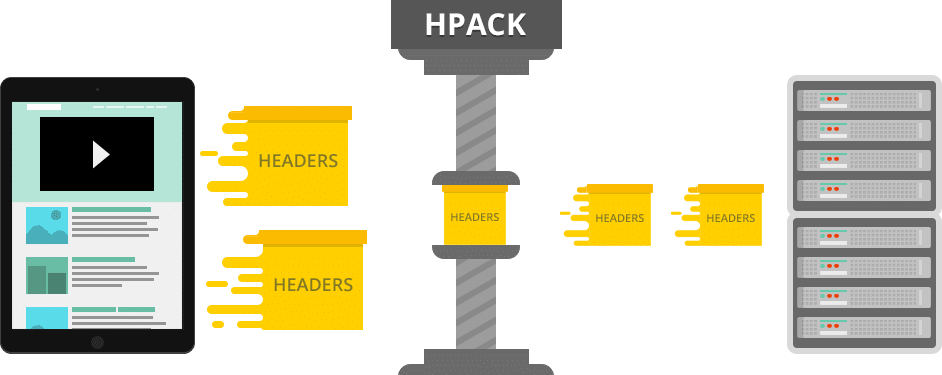
Add to these things HTTP/2’s header HPACK compression and default binary format of data transfer, and we have, in many cases, a significantly more efficient protocol.
Major browser implementations made it a requirement for websites to implement encryption – SSL – to be able to reap the benefits of HTTP/2 – and sometimes this incurred a computation overhead that rendered speed improvements unnoticeable. There were even some cases where users reported slowdown after transitioning to HTTP/2.
Let’s just say that the early days of adoption of this version were not for the weak of heart.
The NGINX implementation also lacked the server-push feature, relying on a module. And NGINX modules are not your usual Apache drop-in modules that you can just copy – NGINX has to be recompiled with these.
While some of these issues are solved now, if we look at the entire protocol stack, we see that the primary constraint lies on a lower level than HTTP/2 dared to venture.
To elaborate this, we will dissect today’s internet protocol stack from its bottom layer to the top. If you want to learn more about the background of HTTP/2, make sure to check out our ultimate HTTP/2 guide.
Internet Protocol (IP)
The Internet Protocol (IP) defines the bottom-part of the entire internet topology. It’s the part of the internet stack that is, we can safely say, really not negotiable without changing everything, including replacing the entire hardware infrastructure, from routers to servers and even the machines of end users.
So, while the protocol overhaul may be due, such a far-reaching endeavor is not on the horizon at this time, mainly because we haven’t come up with a viable, groundbreaking, yet backward-compatible alternative.
Underneath it, there is link layer – the part of the protocol which is “bare metal” so to say.
On a side note, a convincing case for a complete overhaul can be seen from the speed with which creators of IPFS (interplanetary file system) managed to close an ICO funding that made them 250 mil USD within one month.
We can trace the beginnings of the IP protocol back to 1974, to a paper published by the Institute of Electrical and Electronics Engineers and authored by Vint Cerf and Bob Cahn. It detailed packets being sent over a network, routing them across IP addresses, and numerically defined addresses of nodes in a network/networks. The protocol defined the format of these packets, or datagrams – its headers and payload.
After the RFC 760 definition from 1980, the IETF settled with the definition widely used to this day, in its Request For Comments 791. This is the fourth version of the protocol, but we could say it’s the first production version.
It uses 32-bit addresses, which sets constraint to the number of addresses to around 4 billion. This limitation is the explanation for the mystery of why non-business internet users get “dynamic IP addresses” by their ISPs, and a static IP is considered an “added value” and often subject to extra charges.
They are rationing.
It wasn’t long until it was realized that 32-bit addresses are not enough, and the shortage was looming, so many RFCs were published trying to deal with this. Although these solutions are widely used today, and are part of our daily lives, it’s probably safe to say these amount to hacks.
Internet Protocol version 6 or IPv6 came as a way to address these limitations, including to gradually be adopted over the previous version. It was made a Draft Standard document for the IETF in 1998, and was raised to an Internet Standard in 2017.
While IPv4 address space was limited by its 32-bit address length, IPv6 standard was given 128 bits, or 3.4 * 10 ^ 38 possible addresses. This should be enough to last us for quite some time.
According to Google and IPv6 connectivity among its users, IPv6 adoption is just over 25% as of March 2019.